The Canary Deployment Pattern That Actually Works in Production

Why Most Teams Get Canary Deployments Wrong

Three months ago, I watched a team’s “canary deployment” take down their entire e-commerce platform during Black Friday prep. They had configured their ingress controller to route 5% of traffic to the new version, but they hadn’t considered that their payment processing microservice was stateful. When the canary pods started writing to the same database tables as the stable version, data corruption cascaded through their order management system within minutes.

This scenario happens more often than most teams admit. Kubernetes makes it easy to spin up multiple versions of your application, but the real complexity comes from understanding how your services interact at the data layer. The most overlooked aspect of canary deployments isn’t the traffic splitting mechanism itself, but the careful coordination of stateful dependencies and shared resources.

Blue-Green Deployments: The Underrated Workhorse

While everyone talks about canary deployments, blue-green is still the most reliable strategy for services that handle critical business logic. I’ve implemented this pattern across financial services platforms where downtime costs millions per minute. The approach means maintaining two identical production environments and switching traffic instantly between them using DNS or load balancer configuration changes.

The secret to effective blue-green deployments is your database migration strategy. You need to design schema changes that are backward-compatible for at least one deployment cycle. This means additive changes only, no column drops or data type modifications. I typically use a three-phase approach: deploy the new schema alongside the old, migrate data in the background, then clean up deprecated columns in the next release. Kubernetes Jobs work particularly well for the data migration phase, giving you retry logic and completion tracking out of the box.

Resource requirements double during the switchover window, but the operational simplicity more than makes up for it. Your monitoring stack sees clean metrics because you’re never running mixed versions at the same time. Rollbacks happen in seconds rather than minutes, and you can validate the entire system end-to-end before cutting over traffic.

Rolling Updates: When Gradual Makes Sense

Rolling updates work great for stateless services with well-defined health checks, especially when you’re dealing with large replica counts. I’ve found them most effective for API gateways, static content servers, and computational workloads that don’t maintain persistent connections. The key is tuning the maxUnavailable and maxSurge parameters based on your actual traffic patterns rather than accepting Kubernetes defaults.

For a service handling 10,000 requests per second, I typically set maxUnavailable to 25% and maxSurge to 50%. This creates a brief period where you’re running 150% of your normal pod count, but it minimizes the time window where capacity drops. The readiness probe configuration becomes critical here. I use a three-tier health check: basic HTTP response, dependency connectivity verification, and a lightweight business logic test that confirms the service can actually process requests.

The most common failure mode I’ve encountered with rolling updates involves connection draining. Kubernetes sends a SIGTERM to pods being terminated, but many applications don’t handle graceful shutdown properly. Getting signal handling right and configuring terminationGracePeriodSeconds based on your actual request processing times prevents dropped connections during deployments.

Advanced Patterns: Traffic Shadowing and Ring Deployments

Traffic shadowing is the most sophisticated deployment strategy I’ve implemented, particularly valuable for machine learning services where prediction accuracy can only be measured against real user behavior. Using Envoy proxy’s traffic mirroring capabilities, you can send a copy of production traffic to your new version while serving responses from the stable version. This approach revealed performance regressions in our recommendation engine that synthetic testing had missed entirely.

Ring deployments offer another compelling pattern for large-scale systems. You deploy changes to increasingly critical environments: developer clusters first, then internal tools, followed by less critical customer-facing services, and finally core production workloads. I’ve used this approach successfully in platforms serving hundreds of millions of users. Each ring acts as a validation gate, with automated promotion based on error rates, latency percentiles, and business metrics.

The implementation requires careful namespace organization and RBAC policies. I create separate namespaces for each deployment ring with distinct service accounts and network policies. GitOps tools like ArgoCD work exceptionally well here, allowing you to define promotion criteria declaratively and maintain audit trails of deployment progression across rings.

Monitoring and Observability: The Make-or-Break Factor

No deployment strategy succeeds without comprehensive observability. I’ve learned to monitor three distinct layers: infrastructure metrics, application performance, and business impact. Kubernetes provides excellent infrastructure visibility through metrics-server and kube-state-metrics, but application-level monitoring requires more thoughtful design.

Golden signals become your primary decision-making tool during deployments. For web services, I track request latency (95th and 99th percentiles), error rate, and throughput. But the business metrics often matter more: conversion rates, payment success rates, or user engagement depending on your domain. I use Prometheus recording rules to pre-aggregate these metrics, enabling sub-second alerting when deployments impact user experience.

Service mesh technologies like Istio provide deployment-specific metrics that traditional monitoring misses. You can track success rates and latency distributions per deployment version, making it easy to spot regressions early in the rollout process. The circuit breaker patterns built into service meshes also provide automatic failure isolation, preventing deployment issues from cascading across your entire system.

The deployment patterns that work in production are rarely the ones that sound exciting in conference talks. They’re the boring, well-tested approaches that prioritize reliability over cleverness. What deployment challenges has your team faced, and which patterns have proven most reliable in your environment?
Blue-Green Deployments Are Overrated: Why Rolling Deployments Should Be Your Default Strategy

The Industry’s Love Affair with Blue-Green is Missing the Point

After deploying production Kubernetes clusters for the better part of a decade, I’ve watched teams consistently reach for blue-green deployments as their go-to strategy. It’s become the default recommendation in conference talks and blog posts. Yet in my experience managing clusters that serve hundreds of millions of requests daily, blue-green deployments solve the wrong problem for most organizations.

Blue-Green Deployments Are Overrated: Why Rolling Deployments Should Be Your Default Strategy

The appeal is obvious. Blue-green gives you that satisfying feeling of complete control. You spin up an entirely new environment, validate everything works perfectly, then flip a switch. If something goes wrong, you flip it back. Clean, simple, and conceptually elegant. But this elegance comes at a cost that most teams don’t fully appreciate until they’re deep into production operations.

Resource utilization becomes your first enemy. Running two complete environments means doubling your compute costs during deployments. For organizations running lean infrastructure budgets, this alone can be prohibitive. More importantly, managing state synchronization between environments creates failure modes that are often worse than the problems blue-green was meant to solve.

Illustration for Blue-Green Deployments Are Overrated: Why Rolling Deployments Should Be Your Default Strategy

Rolling Deployments: The Underappreciated Workhorse

Rolling deployments get dismissed as “basic” or “risky,” but this misses their fundamental strength. They work with Kubernetes’ natural patterns instead of fighting against them. When you configure a rolling deployment correctly, you’re leveraging the scheduler’s understanding of your cluster’s resource constraints and pod distribution patterns.

The key insight that took me years to fully grasp: rolling deployments force you to build applications that are genuinely resilient. When your application can handle a rolling deployment gracefully, it can handle almost any real-world failure scenario. Node failures, network partitions, resource exhaustion. These all look remarkably similar to a controlled rolling update from your application’s perspective.

I’ve seen teams spend months perfecting their blue-green automation only to have their applications fail catastrophically during a routine node replacement. Their apps worked fine in the controlled blue-green environment but couldn’t handle the messier realities of production infrastructure. Rolling deployments expose these weaknesses during every deployment, forcing you to address them systematically.

The Configuration Details That Actually Matter

Most teams get rolling deployments wrong because they accept the defaults without understanding what they mean. The default maxUnavailable setting of 25% might seem conservative, but it can create cascading failures in tightly coupled systems. I typically start new teams with maxUnavailable set to 1 and maxSurge set to 1, then tune based on what we see in practice.

Readiness and liveness probes become absolutely critical with rolling deployments. Your readiness probe needs to check not just that your application started, but that it’s actually ready to handle production traffic. This means checking database connections, cache warmup, and any other dependencies that could cause request failures. The difference between a 5-second and 30-second readiness check can determine whether your rolling deployment completes smoothly or triggers a cascade of pod restarts.

Pod disruption budgets are where rolling deployments really shine compared to blue-green alternatives. When you set a PDB that ensures at least 80% of your pods remain available during any disruption, you’re not just protecting against deployments. You’re protecting against node maintenance, cluster upgrades, and infrastructure failures. Blue-green deployments bypass these protections entirely, which feels risky to me.

When Blue-Green Actually Makes Sense

I’m not categorically against blue-green deployments. There are specific scenarios where they become the right choice, but these are narrower than most teams realize. Applications with significant database schema changes that require careful migration orchestration can benefit from blue-green’s clear environment separation. Legacy applications that can’t be easily modified to handle graceful shutdowns might need the clean cutover that blue-green provides.

Financial services and other highly regulated environments sometimes require the audit trail and rollback guarantees that blue-green deployments offer. When your deployment process itself needs to be compliance-auditable, the clear separation between environments can simplify your regulatory story significantly.

However, even in these cases, I’ve found that investing in making applications more rolling-deployment-friendly often provides better long-term value than building sophisticated blue-green automation. The operational resilience you gain from applications that handle gradual state changes gracefully pays dividends far beyond deployment scenarios.

The Real-World Performance Numbers

After tracking deployment metrics across multiple organizations, the numbers consistently favor well-configured rolling deployments. Mean time to deployment for rolling updates averages 3-7 minutes depending on cluster size, while blue-green deployments typically take 15-30 minutes once you account for environment provisioning and validation steps.

More importantly, the failure recovery characteristics are fundamentally different. When a rolling deployment fails, you typically have 70-90% of your capacity still running the previous version. When a blue-green deployment fails, you’re often looking at extended downtime while you troubleshoot the new environment or coordinate a rollback that affects 100% of your traffic simultaneously.

Resource efficiency tells an even starker story. Rolling deployments typically peak at 110-125% of steady-state resource usage during the deployment window. Blue-green deployments hit 200% by definition, and often higher once you account for running parallel environments with separate load balancers, databases, and supporting services.

I’ve been refining these deployment strategies across everything from early-stage startups to Fortune 500 enterprises, and the patterns that emerge are remarkably consistent. If you’re currently defaulting to blue-green deployments, I’d encourage you to revisit that decision with fresh eyes. The operational simplicity and resource efficiency of rolling deployments might surprise you, and the application resilience benefits will serve you well beyond your deployment pipeline.

The Mechanics of Senior Engineering Mentorship: What Actually Works After Two Decades in the Field

Understanding the Weight of Technical Guidance

After twenty years of building distributed systems, debugging production failures at 3 AM, and watching talented engineers either flourish or burn out, I’ve learned that mentorship in our field carries a different weight than in most professions. When a junior engineer takes your architectural advice, they’re not just following suggestions. They’re betting their next six months on your judgment about whether microservices will solve their scaling problem or create a distributed monolith that haunts them for years.

The Mechanics of Senior Engineering Mentorship: What Actually Works After Two Decades in the Field

The stakes matter because our industry moves fast enough that bad technical decisions compound quickly. I’ve seen promising engineers lose confidence after implementing patterns that seemed elegant in theory but became maintenance nightmares in practice. The mentor’s responsibility isn’t just to share knowledge, but to calibrate the risk tolerance of guidance based on what the mentee can actually handle and what the system can tolerate.

This calibration requires a different approach than traditional mentorship models suggest. Generic advice about “being available” or “asking good questions” misses the technical depth required. When a mid-level engineer asks whether to use Redis or PostgreSQL for session storage, your answer needs to account for their team’s operational maturity, their current monitoring capabilities, and the specific failure modes each choice introduces. Cheerleading doesn’t prepare them for the 2 AM page when Redis runs out of memory.

Illustration for The Mechanics of Senior Engineering Mentorship: What Actually Works After Two Decades in the Field

Building Technical Intuition Through Controlled Exposure

The most effective mentorship I’ve provided involves deliberately exposing engineers to failure modes in low-stakes environments. This means creating opportunities for them to experience the downstream effects of their architectural decisions without the pressure of production incidents. I learned this approach after watching too many bright engineers make the same scaling mistakes I made fifteen years ago, even with access to all the right documentation and best practices.

Practical implementation looks like pairing on code reviews where you walk through not just what’s wrong, but why the current approach will create problems three months from now when traffic doubles. It means letting them design the monitoring strategy for a new service, then showing them how to simulate the failure conditions that will actually matter. Most importantly, it involves sharing the mental models you use to evaluate trade-offs rather than just the conclusions you’ve reached.

I structure these learning experiences around specific technical scenarios rather than abstract principles. Instead of explaining “design for failure,” I’ll have them trace through what happens when the authentication service goes down during peak traffic. We’ll map out the cascade effects, identify the circuit breakers that should trigger, and discuss why graceful degradation requires more upfront design work than most teams budget for. This concrete approach builds the pattern recognition they’ll need when facing similar situations on their own.

The Art of Incremental Challenge Escalation

Effective mentorship requires understanding the difference between productive struggle and overwhelming complexity. I’ve found that engineers develop best when facing challenges that stretch their current capabilities by roughly 20-30%. Too little challenge and they don’t build new neural pathways. Too much and they retreat to cargo-cult programming, copying patterns without understanding the underlying principles.

The key is recognizing where each engineer sits on the complexity curve and adjusting accordingly. A junior engineer might struggle with understanding why database indexes matter for query performance. That same concept becomes trivial for someone ready to tackle distributed consensus algorithms. The mentor’s job is continuously recalibrating the difficulty level as the engineer’s capabilities expand.

This escalation works best when tied to real project needs rather than artificial exercises. I prefer assigning ownership of increasingly complex system components, starting with well-isolated services that have clear interfaces and moving toward pieces that require understanding cross-cutting concerns. The engineer gets to see how their code behaves under real load patterns, learns to interpret actual monitoring data, and experiences the full lifecycle from design through maintenance.

The progression typically follows a pattern: isolated feature development, then cross-service integration work, followed by ownership of system reliability concerns, and finally architectural decision-making for new initiatives. Each stage builds on previous knowledge while introducing new categories of complexity. The timing of these transitions matters more than the specific technical skills being developed.

Navigating the Politics of Technical Leadership

One aspect of senior engineering that gets little documentation is how technical decisions intersect with organizational dynamics. The most technically sound solution often isn’t the one that gets implemented, and preparing engineers for this reality requires discussing the non-technical factors that influence technical choices. This includes budget constraints, team skill gaps, regulatory requirements, and the political capital required to drive change.

I’ve learned to share not just the technical reasoning behind architectural decisions, but the organizational context that shaped them. When we chose a particular database technology, it wasn’t purely about performance characteristics. It was also about our team’s existing expertise, the vendor relationship we needed to maintain, and the timeline constraints imposed by a compliance deadline. Understanding these factors helps engineers make better recommendations that account for implementation feasibility.

This political awareness becomes essential as engineers move into senior roles where their technical judgment carries organizational weight. They need to understand how to build consensus around technical decisions, communicate trade-offs to non-technical stakeholders, and recognize when perfectly good technical solutions will fail because of organizational resistance. These skills aren’t taught in computer science programs, but they determine whether an engineer’s technical expertise translates into effective leadership.

Creating Sustainable Mentorship Practices

The mentorship approaches that worked early in my career don’t scale when you’re responsible for the technical growth of entire teams. The intensive one-on-one model that many engineers expect becomes unsustainable when you have more than three or four direct mentorship relationships. I’ve had to develop systems that multiply my impact while maintaining the depth of guidance that actually changes how engineers think about problems.

Group mentorship sessions focused on specific technical challenges work well for this scaling problem. Rather than explaining the same architectural pattern to multiple engineers separately, I’ll bring together everyone working on related problems and walk through the design considerations together. This creates opportunities for peer learning while ensuring consistent technical guidance across the team.

Documentation of decision-making processes becomes essential at this scale. I maintain technical decision records not just for future reference, but as teaching tools that show how experienced engineers evaluate trade-offs. These records capture not just what was decided, but why alternatives were rejected, what assumptions were made, and what monitoring will validate the choice. They become a curriculum for understanding how technical judgment develops over time.

The most sustainable mentorship happens when senior engineers create systems that help others learn independently. This means building code review processes that teach rather than just catch errors, designing monitoring that reveals system behavior patterns, and creating documentation that explains not just how to use systems but how to reason about their failure modes. The goal is developing engineers who can make sound technical decisions without needing constant guidance.

These approaches have evolved through years of trial and error, shaped by the specific challenges of our field and the changing nature of technical leadership. I’m curious about your experiences with technical mentorship, particularly the methods you’ve found effective for building the kind of deep technical intuition that separates good engineers from great ones.

Why Your First Database Query Takes 3 Seconds and Your Thousandth Takes 30 Milliseconds

I watched a junior developer stare at their monitor last Tuesday, confused why their application felt sluggish during user testing but screamed during development. The difference wasn’t the code. It was the data. In development, their users table had twelve rows. In staging, it had 847,000. That’s when database performance stops being theoretical and becomes the thing that wakes you up at 3 AM.

Database optimization isn’t about memorizing arcane SQL tricks or buying faster hardware. It’s about understanding how your data grows, how your queries behave under load, and building systems that scale gracefully from day one. The patterns you establish with your first thousand records will determine whether your application handles your first million records or crashes spectacularly trying.

Start With Indexes, But Not All Of Them

The most common mistake I see isn’t missing indexes. It’s creating too many indexes without understanding their cost. Every index you add speeds up reads but slows down writes. Your users table might need an index on email for login lookups, but it probably doesn’t need indexes on first_name, last_name, created_at, and status all at once.

Focus on your application’s critical paths. If users log in with email addresses, index that field. If your dashboard shows recent orders, index the orders table by created_at and user_id as a composite index. Start simple: CREATE INDEX idx_users_email ON users(email). Monitor your slow query logs for a week. Add indexes only when you see genuine performance problems, not preemptively.

I learned this lesson the hard way maintaining an e-commerce platform where the previous team had indexed everything. Inserts were taking 200ms because PostgreSQL was maintaining fourteen indexes on a products table. We dropped eight indexes that were never used in queries. Insert time dropped to 15ms, and search performance actually improved because the query planner could make better decisions with fewer options.

Query Patterns Matter More Than Query Optimization

The fastest query is often not the cleverest one. It’s the one that fetches exactly what you need, when you need it, in a predictable way. I’ve seen developers write beautiful recursive CTEs that brought production databases to their knees. Meanwhile, simple JOIN queries processed millions of rows efficiently because they followed predictable access patterns.

Take pagination. The naive approach uses OFFSET: SELECT * FROM posts ORDER BY created_at DESC LIMIT 20 OFFSET 1000. This scans and discards 1000 rows every time. For page 50 of results, you’re scanning 1000 rows to show 20. Cursor-based pagination using WHERE created_at < '2023-10-15' ORDER BY created_at DESC LIMIT 20 scans only the rows you need.

The difference becomes stark at scale. OFFSET pagination on a million-row table might take 500ms for page 1000. Cursor pagination takes the same 5ms regardless of position because it uses the index directly. Your users won’t wait for slow pagination, but they’ll happily scroll through fast, consistent results.

Connection Pooling Isn’t Optional Above Toy Scale

Database connections are expensive. Each connection consumes memory on your database server, typically 2-8MB per connection. More critically, most databases perform poorly with too many concurrent connections. PostgreSQL’s performance degrades significantly above 100-200 active connections. MySQL shows similar patterns.

Connection pooling solves this by maintaining a fixed number of database connections that your application shares. Instead of opening a connection for each request, your application borrows a connection from the pool, executes its queries, and returns the connection for reuse. PgBouncer for PostgreSQL or MySQL’s built-in connection pooling can handle hundreds of application connections with just 20-30 database connections.

I’ve watched applications fail during traffic spikes not because of CPU or memory constraints, but because they exhausted database connections. A Rails application I maintained was opening 5-10 connections per request due to poor Active Record configuration. Under load, it would exhaust PostgreSQL’s connection limit of 100, causing cascading failures. Configuring PgBouncer with a pool size of 25 connections handled 10x the traffic without breaking a sweat.

Measure First, Optimize Second

Database optimization without measurement is just guessing with extra steps. Your database provides detailed metrics about query performance, index usage, and resource consumption. PostgreSQL’s pg_stat_statements extension shows you exactly which queries consume the most time. MySQL’s performance_schema provides similar insights. Use them.

Start by identifying your top 5 slowest queries over a representative time period. Don’t optimize based on development data or synthetic benchmarks. Real user patterns reveal surprising bottlenecks. That admin report that runs once a month might be your slowest query, but optimizing the login query that runs 10,000 times per hour will have more impact on user experience.

Enable slow query logging with a threshold that catches queries taking longer than 100ms. In PostgreSQL, set log_min_duration_statement = 100. Watch your logs for a week. The patterns that emerge will guide your optimization efforts better than any generic advice. I once spent days optimizing a complex analytics query only to discover that a simple SELECT COUNT(*) on an unindexed status column was causing 90% of our performance issues.

Building Systems That Grow With You

The database optimizations that matter aren’t the exotic ones. They’re the foundational patterns that let your application scale predictably as your data grows. Index your critical paths but don’t over-index. Write queries that use indexes effectively. Pool your connections. Measure your performance continuously.

These aren’t one-time optimizations. They’re practices that compound over time. The monitoring you set up today will catch performance regressions next month. The connection pooling you configure now will handle next quarter’s traffic spike. The query patterns you establish with thousand-row tables will work with million-row tables.

Look at what patterns you’re building into your application right now. Are your queries going to work when your data is 100x larger? Have you instrumented enough to catch problems before your users do?

Lessons from Twenty Years of Breaking Things: How Security Assessment Methodologies Actually Work in Practice

The Evolution of How We Find What’s Broken

When I started doing security assessments in the early 2000s, our methodology was basically “throw everything at the wall and see what sticks.” We’d run Nessus, maybe some custom scripts, and spend weeks manually poking at applications. The industry has grown up a lot since then, but I’ve watched too many organizations get caught up in framework acronyms while missing the basics that actually matter.

Lessons from Twenty Years of Breaking Things: How Security Assessment Methodologies Actually Work in Practice

The truth is that effective vulnerability assessment isn’t about following a checklist or implementing the latest methodology du jour. It’s about understanding systems deeply enough to know where they’re likely to fail, then systematically proving or disproving those hunches. Over the years, I’ve seen OWASP methodologies, NIST frameworks, and proprietary approaches come and go. What remains constant is the need for structured thinking combined with deep technical understanding.

The best assessments I’ve conducted always started with threat modeling, even when we didn’t call it that. We’d sit with the development team and operations folks, sketch out data flows on whiteboards, and identify the components that would be most attractive to attackers. This collaborative approach revealed more critical vulnerabilities than any automated scanner ever did, because it helped us understand the business context and the specific ways the system could be abused.

Illustration for Lessons from Twenty Years of Breaking Things: How Security Assessment Methodologies Actually Work in Practice

Why Automated Tools Are Both Essential and Insufficient

I’ve run probably every commercial and open-source vulnerability scanner that’s existed in the past two decades. Nessus, OpenVAS, Rapid7, Qualys, custom Python scripts that grew into monsters over time. Each has its place, but none of them think like an attacker. They’re excellent at finding known vulnerabilities in standard configurations, but they miss the subtle logic flaws and business process vulnerabilities that cause the most damage.

The real value of automated scanning isn’t in the initial results, it’s in the trending and coverage verification. I’ve seen organizations run weekly Nessus scans and pat themselves on the back for having “good security hygiene,” while completely missing SQL injection vulnerabilities in their custom applications. Scanners give you a baseline and help ensure you’re not missing obvious problems, but they can’t replace human analysis of how systems actually work.

What changed my approach was realizing that automated tools should inform manual testing, not replace it. I started using scanner results to understand the attack surface and identify interesting entry points, then spending my time on the analysis that machines can’t do. This mixed approach consistently found more critical vulnerabilities than either pure automation or pure manual testing alone.

The Human Element: What Twenty Years of Code Review Taught Me

Static analysis tools have improved dramatically, but they still can’t understand business logic. I remember reviewing a financial application where the automated tools flagged dozens of low-priority issues but completely missed the fact that negative account balances weren’t properly validated. A simple request manipulation could create money from nothing, but no scanner would ever find that because it required understanding what the application was supposed to do.

The most effective code review sessions I’ve been part of involved developers, security engineers, and business stakeholders in the same room. We’d walk through critical functions line by line, with developers explaining the intended behavior and security folks identifying potential failure modes. This collaborative approach catches entire classes of vulnerabilities that traditional assessment methodologies miss.

I learned to focus code review efforts on authentication mechanisms, authorization logic, input validation boundaries, and data flow between trust boundaries. These areas consistently yielded the highest-impact findings. Spending hours reviewing routine CRUD operations rarely produced actionable results, but thirty minutes analyzing how the application handles role escalation often revealed critical flaws.

Penetration Testing: Beyond the Exploitation Theater

Early in my career, penetration testing felt like controlled hacking. We’d exploit vulnerabilities, demonstrate impact, and write reports about what we’d compromised. While that approach has its place, I’ve found that the most valuable pen tests focus on understanding and documenting attack paths rather than simply proving that exploitation is possible.

The best penetration tests I’ve conducted started with threat modeling and ended with specific remediation guidance. Instead of trying to compromise as many systems as possible, we’d identify the most likely attack scenarios based on the organization’s threat model, then systematically test those paths. This approach provided much more actionable intelligence than traditional “find and exploit everything” methodologies.

What really changed my perspective was working with incident response teams and seeing how actual attacks unfold. Real attackers don’t use Metasploit to pop shells for sport. They identify specific business objectives, research the target organization, and develop focused approaches to achieve their goals. Our testing methodologies should mirror that level of intentionality and business context.

Building Sustainable Assessment Programs

The organizations with the most effective security assessment programs don’t rely on annual penetration tests or quarterly vulnerability scans. They build assessment activities into their development lifecycle and operations processes. This means lightweight threat modeling during design phases, automated security testing in CI/CD pipelines, and regular architecture reviews when systems change.

I’ve seen too many companies treat security assessment as a compliance checkbox rather than a tool for actually improving security. The most successful programs I’ve helped implement focus on continuous improvement rather than point-in-time validation. They use assessment results to guide security investments, inform developer training, and evolve their threat models as the business changes.

The key insight that took me years to understand is that methodology matters less than consistency and context. Whether you use OWASP, NIST, or a custom framework isn’t as important as applying it consistently and adapting it to your specific environment. The best assessment methodology is the one that your team will actually follow and that produces actionable results for your organization.

After two decades of breaking things professionally, I’m convinced that effective security assessment is more craft than science. If you’re building or improving an assessment program, I’d be interested to hear about your experiences and the approaches that have worked in your environment.

Building Your First Distributed System: A Practical Guide to Architecture Patterns That Actually Work

Why Distributed Systems Feel Impossible Until They Don’t

After fifteen years of building systems that span continents and handle millions of requests, I’ve watched countless developers stare at distributed architecture diagrams with the same expression I probably had when I first encountered them. The boxes and arrows look deceptively simple until you realize each arrow represents a potential failure point, and each box contains assumptions that will betray you at 3 AM on a Saturday.

Building Your First Distributed System: A Practical Guide to Architecture Patterns That Actually Work

The truth is that distributed systems aren’t complex because engineers enjoy suffering. They’re complex because they solve genuinely hard problems: maintaining consistency across unreliable networks, ensuring availability when hardware fails, and scaling beyond what any single machine can handle. But here’s what I wish someone had told me when I started: you don’t need to solve all these problems at once.

The insight that changed everything for me came during a particularly brutal outage in 2018. While debugging a cascade failure across twelve microservices, I realized we had built a distributed system by accident. We started with a monolith, carved out a few services to solve immediate scaling bottlenecks, and suddenly found ourselves managing a network of interdependent components without any coherent strategy. That’s when I learned that successful distributed systems aren’t built through gradual decomposition. They’re designed with clear patterns from the beginning.

Illustration for Building Your First Distributed System: A Practical Guide to Architecture Patterns That Actually Work

Start With the Load Balancer Pattern

If you’re going to build your first distributed system, start with the simplest pattern that actually teaches you something useful: the load balancer pattern. Take your existing application, deploy multiple identical instances behind a load balancer, and watch what breaks. This sounds almost trivial, but it immediately exposes every assumption your application makes about local state, shared resources, and session management.

I recommend starting with a simple round-robin load balancer, not because it’s the best algorithm, but because it’s predictable and debuggable. Use something like HAProxy or nginx, configure health checks that actually test your application’s readiness, and monitor response times across all instances. Within a week, you’ll discover that your application wasn’t as stateless as you thought. You’ll start thinking about where data lives and how it flows between components.

What I love about this pattern is that it scales your understanding along with your system. You’ll naturally encounter session affinity problems, learn about connection pooling, and start thinking about graceful degradation. When one instance starts responding slowly, you’ll see how it affects the entire pool. When you need to deploy updates without downtime, you’ll discover blue-green deployments. Each challenge builds on the previous one, creating a foundation for more complex patterns.

Database Replication Teaches You About Consistency

Once you’re comfortable with multiple application instances, the next pattern to master is database replication. This is where distributed systems get philosophically interesting because you’re forced to confront the fundamental tension between consistency and availability. Set up a primary database with one or more read replicas, direct your read traffic to the replicas, and prepare to learn about eventual consistency the hard way.

The first time you update a user’s profile and immediately redirect to a page that shows the old information, you’ll understand why read-after-write consistency matters. The first time a replica falls behind during high write traffic and your application starts showing stale data, you’ll appreciate why monitoring replication lag is critical. These aren’t abstract concepts when they’re breaking your application in real-time.

Start with MySQL or PostgreSQL replication, not because they’re the most sophisticated options, but because they’re well-documented and widely supported. Configure your application to route reads and writes appropriately, implement connection pooling to manage the additional database connections, and build monitoring that tracks both query performance and replication health. This pattern will teach you more about distributed systems than any amount of reading about CAP theorem.

Pay particular attention to how you handle replica failures. When a read replica goes down, does your application gracefully fall back to the primary, or does it start throwing errors? When the primary fails and you need to promote a replica, how long does that process take, and what happens to your application during the transition? These scenarios will happen in production. Experiencing them in a controlled environment builds the intuition you need for more complex systems.

Event-Driven Architecture for Loose Coupling

After you’ve mastered stateless applications and database replication, you’re ready for event-driven architecture. This pattern fundamentally changes how your components communicate, moving from synchronous request-response to asynchronous message passing. It’s more complex to implement correctly, but it’s also more resilient and scalable than direct service-to-service communication.

Start with a simple message queue like RabbitMQ or Amazon SQS. Pick one business process in your application, something like user registration or order processing, and implement it using events instead of direct database writes. When a user registers, publish a “UserRegistered” event. Have separate consumers that handle email verification, account setup, and analytics tracking. This forces you to think about message ordering, duplicate handling, and failure recovery.

The first challenge you’ll encounter is exactly-once processing. Messages will be delivered multiple times. Consumers will crash while processing events. You’ll need to make your handlers idempotent. This is where you’ll learn about message acknowledgments, dead letter queues, and the importance of including enough context in each event to process it independently.

Event-driven architecture also teaches you about system observability in ways that synchronous systems don’t. When a user registration takes five seconds, is the delay in the email service, the analytics service, or the message queue itself? You’ll need distributed tracing, correlation IDs, and careful attention to message timestamps. These skills directly transfer to more complex patterns like microservices and CQRS.

Caching Strategies That Scale

The final pattern I recommend mastering before moving to more advanced architectures is distributed caching. Caching seems simple until you’re debugging cache invalidation bugs at scale, trying to figure out why some users see updated data while others are stuck with stale information for hours.

Start with Redis or Memcached as an external cache layer. Begin by caching expensive database queries, but pay close attention to cache key design and invalidation strategies. Use cache-aside pattern initially, where your application explicitly manages what goes in and out of the cache. This gives you complete control and helps you understand the tradeoffs between cache hit rates and data consistency.

The real education comes when you start caching at multiple layers. Add HTTP caching headers for static content, implement application-level caching for computed results, and use database query caching for frequently accessed data. Now you have a distributed caching hierarchy, and you need to think about cache coherence, invalidation cascades, and the performance implications of cache misses.

Watch what happens when your cache cluster fails. Does your application gracefully degrade to handling uncached requests, or does it fall over because it can’t handle the database load? This scenario will teach you about circuit breakers, bulkhead patterns, and the importance of designing for failure from the beginning.

These four patterns form the foundation of every distributed system I’ve built. Master them first, understand their failure modes, and build the operational muscle memory for monitoring and debugging them. Once you’re comfortable with load balancing, replication, events, and caching, you’ll find that more complex patterns like microservices and event sourcing are really just sophisticated combinations of these building blocks. The path from here leads through service meshes, distributed databases, and eventually to the kind of large-scale systems that initially seemed impossible. But that’s a journey for another article.

The Four Pillars of CI/CD Pipeline Design That Actually Matter

Start With Failure, Not Success

Most teams design their CI/CD pipelines around the happy path. They optimize for that beautiful green build where every test passes, every deployment succeeds, and the coffee tastes just right. This is backwards thinking that will cost you months of debugging time and countless production incidents.

The Four Pillars of CI/CD Pipeline Design That Actually Matter

Here’s the reality: your pipeline will fail. Code will break, tests will flake, infrastructure will hiccup, and dependencies will disappear into the digital ether. I’ve watched teams spend weeks perfecting their success scenarios only to discover their pipeline becomes a black box the moment something goes wrong. Error handling isn’t an afterthought in pipeline design. It’s the foundation.

Build your pipeline to fail gracefully from day one. This means verbose logging at every stage, clear failure modes that don’t cascade into mysterious subsequent failures, and rollback mechanisms that work when your database is in an inconsistent state. When your deployment fails at 2 AM, you want to know exactly which step broke and why, not spend three hours deciphering cryptic error messages that could mean anything.

I learned this lesson the hard way during a midnight deployment where a single missing environment variable caused our entire pipeline to report success while silently skipping critical database migrations. The deployment “succeeded” but the application was completely broken. We only caught it because a vigilant engineer happened to check the logs manually. That incident led to our current approach: assume failure first, then build for success.

Illustration for The Four Pillars of CI/CD Pipeline Design That Actually Matter

Immutability Is Your Safety Net

Every artifact that flows through your pipeline should be immutable. This sounds obvious until you start working with teams who rebuild Docker images for different environments, or worse, who modify configuration files in place during deployment. These practices create variables that make debugging nearly impossible and introduce subtle differences between environments that only surface during critical moments.

True immutability means your application code, its dependencies, and its configuration are locked in place the moment they enter your pipeline. If you need different behavior in staging versus production, handle it through external configuration or feature flags, not by modifying the artifact itself. The same binary that passes all your tests in staging should be exactly what deploys to production.

This principle extends to your infrastructure definitions as well. Your Terraform files, Kubernetes manifests, and deployment scripts should be versioned and immutable. When a deployment fails, you want to be able to point to an exact commit and say “this is what we tried to deploy” without any ambiguity about what might have changed between environments.

The discipline this requires feels constraining at first, but it pays dividends when you’re troubleshooting production issues. Instead of wondering if something changed during the deployment process, you can focus on the real problems. Immutability eliminates an entire class of “it works on my machine” problems because the machine becomes irrelevant.

Parallel Execution With Smart Dependencies

Speed matters in CI/CD, but not for the reasons most people think. Yes, faster feedback loops improve developer productivity, but the real value of pipeline speed is reliability. Slow pipelines encourage dangerous shortcuts like skipping tests or deploying before the pipeline completes. I’ve seen teams bypass their own safety mechanisms because waiting twenty minutes for a build felt unreasonable.

The key to pipeline speed isn’t throwing more hardware at the problem. It’s understanding which steps can run in parallel and which have genuine dependencies. Most pipelines I encounter run sequentially because it’s easier to reason about, but this approach leaves significant performance on the table.

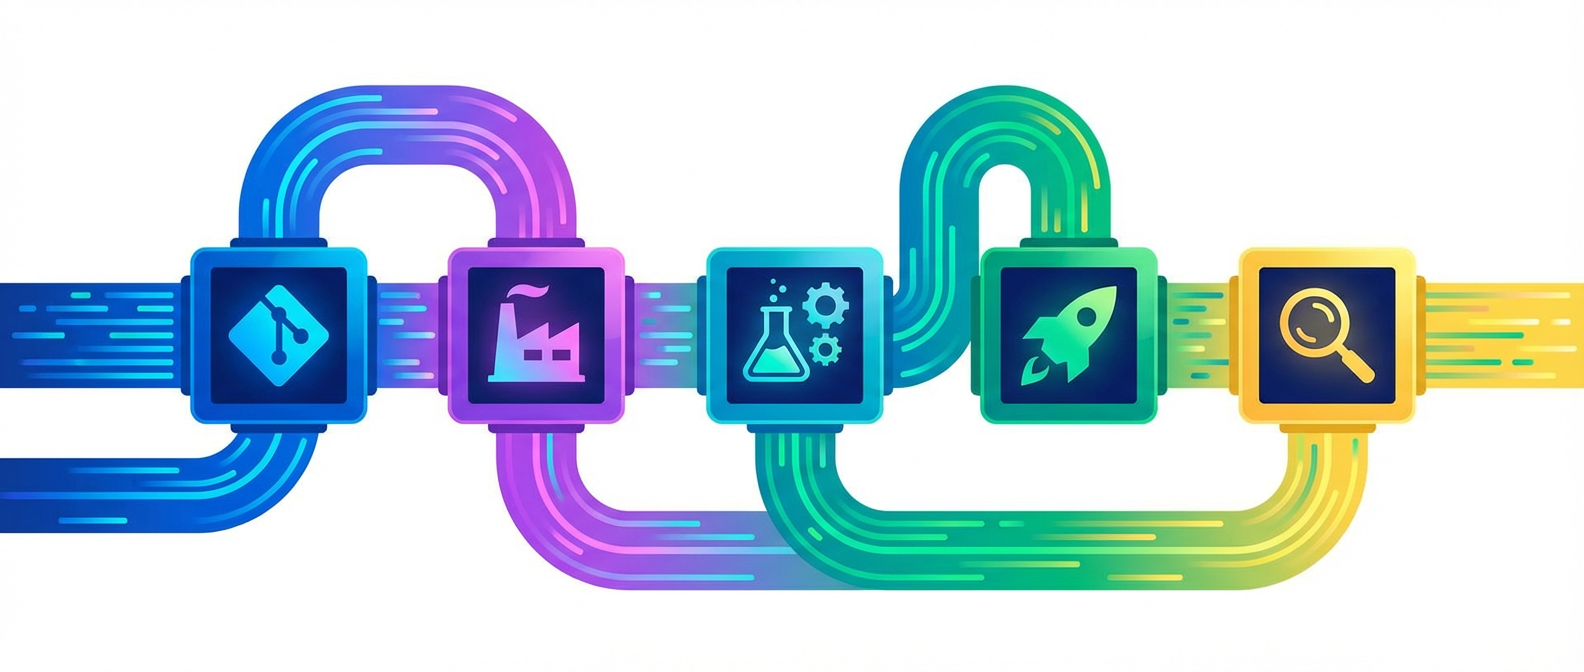
Start by mapping out your pipeline’s actual dependencies. Unit tests probably don’t need to wait for static analysis to complete. Integration tests might depend on your application being built, but they don’t need to wait for security scans. Documentation generation can happen in parallel with almost everything else. Build a dependency graph and let your pipeline runner execute everything it can simultaneously.

The trick is being honest about dependencies. Just because step A happens to run before step B in your current pipeline doesn’t mean B depends on A. I once helped a team reduce their pipeline time from forty minutes to twelve minutes by identifying that their integration tests, security scans, and documentation builds were unnecessarily sequential. The only real dependency was that everything needed the initial compilation step to complete first.

Environment Promotion, Not Configuration

Here’s where most CI/CD strategies fall apart: they treat environments as different configurations of the same system rather than stages in a promotion process. This leads to environment drift, configuration sprawl, and the classic “it works in staging” problem that haunts production deployments.

Instead of configuring different environments, promote identical artifacts through increasingly production-like stages. Your development environment should be a smaller version of production, not a different configuration. Your staging environment should be indistinguishable from production except for scale and data sensitivity. This approach makes your pipeline a validation process rather than a transformation process.

This means investing in infrastructure that supports this model. You need consistent networking, similar load balancing setups, and comparable data stores across environments. Yes, this costs more than running everything on developer laptops and a single staging server, but the reduction in production surprises more than pays for itself.

The promotion model also changes how you think about feature flags and configuration management. Instead of maintaining different configuration files for each environment, you maintain different feature flag states. Your application learns to adapt to its environment at runtime rather than being compiled differently for each stage.

Observability From The Pipeline Itself

Your CI/CD pipeline is infrastructure, and like all infrastructure, it needs monitoring, alerting, and observability. Most teams focus on monitoring their applications while treating their pipelines as black boxes that either work or don’t. This approach leaves you blind to performance degradation, resource constraints, and subtle failures that accumulate over time.

Put metrics in your pipeline stages that actually matter. Track build times by stage, test success rates over time, deployment frequency, and rollback rates. Set up alerts for when pipeline performance degrades or when failure rates spike. These metrics often provide early warning signs of problems in your codebase, infrastructure, or team practices.

The goal isn’t just to know when your pipeline breaks, but to understand why it’s slowing down, which tests are becoming flaky, and how changes in your codebase affect pipeline performance. I’ve used pipeline metrics to identify memory leaks in test suites, infrastructure capacity problems, and even team burnout patterns reflected in code quality trends.

Treat your pipeline like a product that works for your development team. Like any product, it needs user feedback, performance monitoring, and continuous improvement. The teams that embrace this mindset end up with pipelines that actively improve their development process rather than just gatekeeping their deployments.

These principles have guided pipeline designs across teams ranging from five engineers to several hundred, in organizations deploying daily and others pushing code dozens of times per day. The specifics change with scale and technology choices, but the underlying patterns remain consistent. I’m curious about your experiences with pipeline design, particularly where these principles have succeeded or failed in your context.

Why Most Senior Engineer Mentorship Programs Are Broken (And What Actually Works)

The Mentorship Theater Problem

After watching countless “mentorship programs” fail across three decades and half a dozen companies, I’ve noticed something troubling. Most organizations treat senior engineer mentorship like a checkbox exercise, pairing people arbitrarily and expecting magic to happen. The typical approach involves throwing a junior developer at a senior engineer with zero structure, no clear outcomes, and the naive assumption that experience automatically translates to teaching ability.

Why Most Senior Engineer Mentorship Programs Are Broken (And What Actually Works)

The reality hits harder than you’d expect. I’ve seen brilliant architects who can design distributed systems in their sleep completely fumble basic knowledge transfer. I’ve watched junior engineers get paired with seniors who view mentorship as an interruption to their “real work.” The result? Mutual frustration. Wasted time. Junior developers who learn to avoid asking questions altogether.

This isn’t just inefficient. It’s actively damaging. When mentorship fails, it doesn’t just waste the immediate participants’ time. It creates a culture where knowledge hoarding becomes the norm, where tribal knowledge stays locked in senior heads, and where the next generation of engineers learns to figure everything out through painful trial and error.

Illustration for Why Most Senior Engineer Mentorship Programs Are Broken (And What Actually Works)

The Osmosis Fallacy

The biggest myth in engineering mentorship is that proximity equals learning. I call this the “osmosis fallacy” because it assumes junior engineers will absorb expertise simply by sitting near experienced developers. This belief drives the popular “shadow the senior engineer” approach, where mentees observe code reviews, sit in on architecture discussions, and watch debugging sessions.

Here’s what actually happens: the junior engineer watches the senior navigate complex systems using mental models built over years of experience. The senior makes intuitive leaps, references historical context the junior lacks, and operates at a level of abstraction that feels like watching wizardry. The learning value approaches zero because there’s no scaffolding to bridge the knowledge gap.

I’ve tested this repeatedly. Take a junior developer, have them shadow me for a week of debugging production issues, then ask them to tackle a similar problem independently. The failure rate is near 100%. They saw me fix things, but they didn’t understand the diagnostic process, the mental frameworks I used, or the accumulated heuristics that guided my decisions. Observation without structured explanation is just entertainment.

What Actually Works: Deliberate Practice Architecture

Effective mentorship requires treating skill development like engineering itself: you need clear requirements, measurable outcomes, and iterative feedback loops. The most successful approach I’ve developed centers on what I call “deliberate practice architecture” where learning happens through carefully constructed challenges rather than passive observation.

Start with skill breakdown. Instead of vague goals like “learn to be a better engineer,” break down specific capabilities. Can they trace a request through a distributed system? Can they write effective tests for legacy code? Can they identify performance bottlenecks in database queries? Each skill becomes a concrete learning objective with clear success criteria.

Then create controlled complexity. Give them real problems, but with constraints that prevent them from drowning. Want to teach debugging? Don’t throw them into a production outage. Instead, introduce bugs into controlled environments where failure has no consequences but the learning is genuine. I’ve built entire sandbox systems specifically for this purpose, complete with realistic data and intentionally planted issues.

The feedback loop is everything. Schedule regular technical discussions, not status updates. Dig into their thought processes. Ask them to explain their reasoning before revealing the solution. The best learning happens when mentees articulate their mental models out loud, exposing gaps that neither of you realized existed.

The Documentation Discipline

Most mentorship happens in conversations and disappears into the ether. This is wasteful and unsustainable. The best mentoring relationships I’ve seen involve disciplined documentation of both problems and solutions. Not formal documentation that nobody reads, but practical artifacts that become reference material.

I require mentees to maintain decision logs. When they encounter a design choice or technical trade-off, they document their reasoning, the alternatives they considered, and the outcome. This works for multiple reasons: it forces deeper thinking, creates a searchable knowledge base, and reveals patterns in their decision-making that we can address systematically.

Code reviews become teaching documents. Instead of quick approvals or rejections, I write detailed explanations of why certain approaches work better than others. I link to relevant resources, explain the historical context of conventions, and outline the potential future implications of current decisions. Yes, this takes more time upfront, but it creates durable learning that benefits the entire team.

The mentee writes technical postmortems for every significant challenge, whether it’s a bug they fixed or a feature they shipped. The format is simple: what was the problem, how did they investigate, what solution did they choose, and what would they do differently next time. These become invaluable references and reveal knowledge gaps that aren’t obvious during day-to-day work.

Measuring What Matters

Most mentorship programs fail because they don’t measure outcomes effectively. Satisfaction surveys and completion rates tell you nothing about skill development. The metrics that actually matter are harder to capture but far more meaningful.

Track decision quality over time. Can the mentee make increasingly complex technical choices independently? Do their solutions show growing sophistication? Are they catching issues earlier in the development process? I keep informal scorecards of technical decisions and review them quarterly to identify improvement patterns.

Monitor question evolution. Early mentorship involves basic “how do I” questions. As developers mature, questions shift toward “which approach is better” and eventually to “what are the implications of this choice.” The sophistication of questions asked is a reliable indicator of growing expertise.

Evaluate knowledge transfer capability. The ultimate test of understanding is teaching others. I regularly ask mentees to explain concepts to newer team members or to write internal guides on topics they’ve mastered. If they can teach it clearly, they truly understand it.

The feedback cycle isn’t just about the mentee’s growth. I track which mentoring approaches work best for different personality types and experience levels. Some developers thrive on systematic, step-by-step instruction. Others learn better through guided experimentation. Effective mentorship requires adapting your approach based on evidence, not assumptions.

What’s your experience with engineering mentorship? I’m particularly interested in hearing about approaches that didn’t work as expected, since failure cases often reveal more about effective practices than success stories. Drop me a line if you’ve developed your own frameworks or if you’ve seen this problem tackled differently elsewhere.